Field Guides / Kubernetes Autoscaling and Cost
Field Guide · Intermediate to Advanced · 10-12 hours with labsKubernetes Autoscaling and Cost
Make Kubernetes autoscaling boring and your bill smaller: requests, HPA, VPA, KEDA, Karpenter and FinOps, with hands-on labs.
79
pages
pages
11
hands-on labs
hands-on labs
24
interview Q&As
interview Q&As
13
chapters
chapters
This is for you if
- Your HPAs flap, sit at max, or never scale down and you're not sure why
- You own a cluster bill and need to explain or cut it with data
- You're choosing between Cluster Autoscaler, Karpenter, VPA and KEDA
- You're preparing for senior platform, SRE or DevOps interviews
What's inside
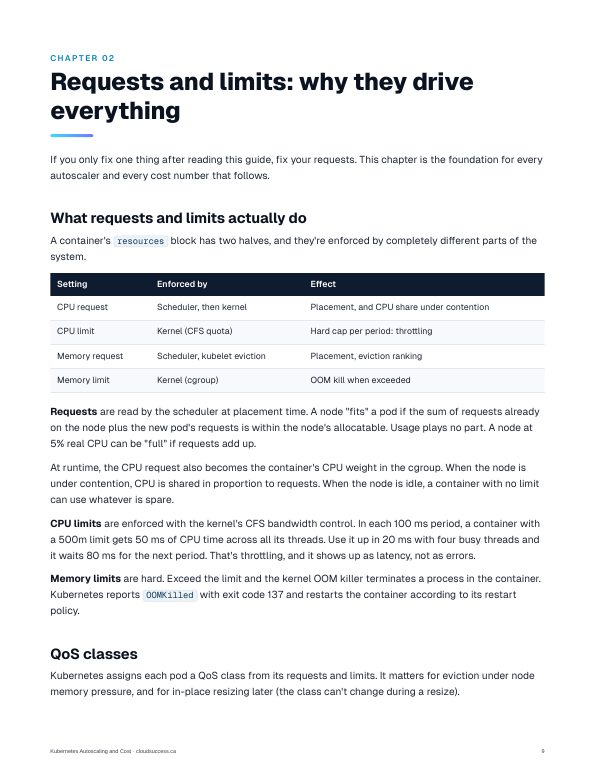
- Why requests drive every autoscaler and cost report, with throttling and OOM kills reproduced and measured
- HPA v2 in depth: the algorithm, resource, container, custom and external metrics, behavior and the tolerance field now stable in 1.37
- VPA modes including InPlaceOrRecreate, and in-place pod resize (stable since Kubernetes 1.35) done by hand
- KEDA scalers, activation vs scaling, and scale to zero with a Redis queue lab
- Cluster Autoscaler vs Karpenter: NodePools, consolidation policies, disruption budgets and spot, plus an optional EKS lab with full teardown
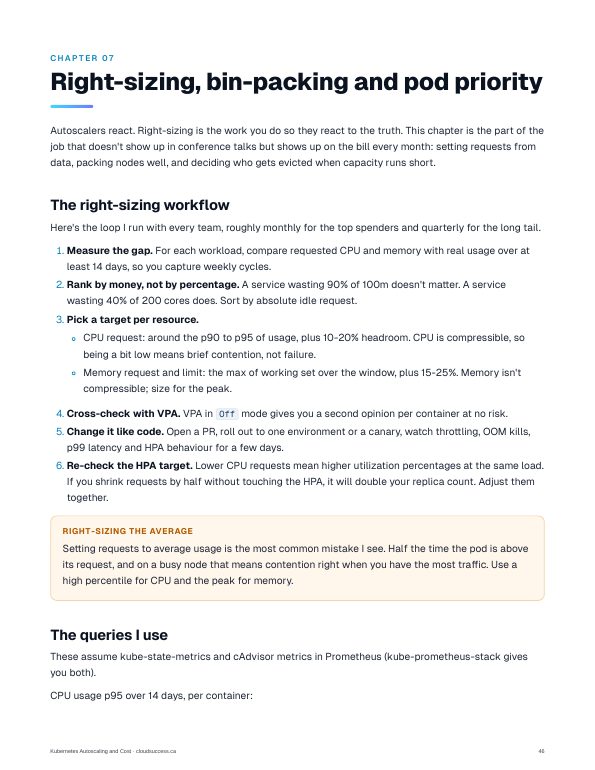
- A right-sizing workflow with PromQL, bin-packing, pod priority, preemption and placeholder headroom
- Cost allocation with OpenCost and FinOps practices that work for platform teams
- Autoscaling pitfalls and a symptom-to-fix troubleshooting playbook with four worked cases
- 24 senior-level interview Q&As, dense cheat sheets and a 30-day practice plan
After this guide you can
- Set requests and limits from data and explain how they drive scheduling, scaling and cost
- Tune HPA behavior so workloads scale fast without thrashing
- Right-size pods with VPA and resize them in place without restarts
- Scale event-driven workloads to zero with KEDA
- Configure Karpenter consolidation, budgets and spot safely
- Find and fix what blocks scale-down, and report cost per team
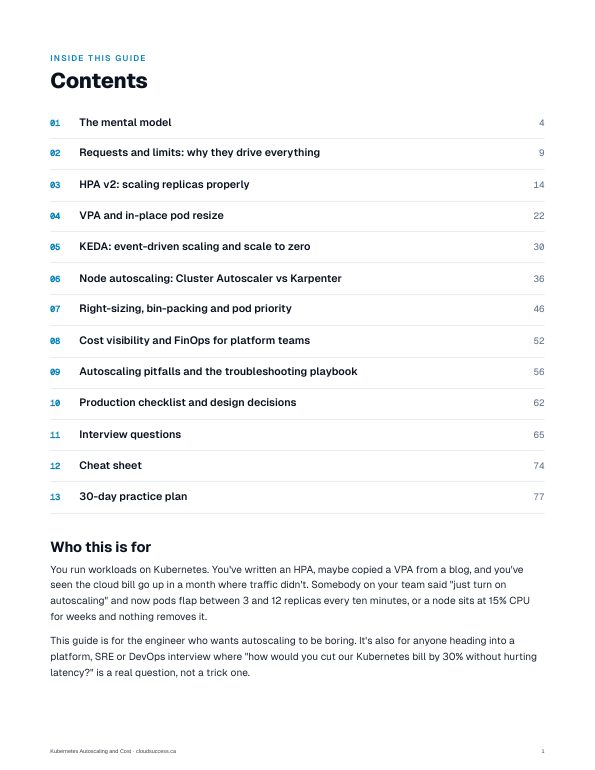
Contents
- The mental modelp. 4
- Requests and limits: why they drive everythingp. 9
- HPA v2: scaling replicas properlyp. 14
- VPA and in-place pod resizep. 22
- KEDA: event-driven scaling and scale to zerop. 30
- Node autoscaling: Cluster Autoscaler vs Karpenterp. 36
- Right-sizing, bin-packing and pod priorityp. 46
- Cost visibility and FinOps for platform teamsp. 52
- Autoscaling pitfalls and the troubleshooting playbookp. 56
- Production checklist and design decisionsp. 62
- Interview questionsp. 65
- Cheat sheetp. 74
- 30-day practice planp. 77
Written by Randy, a Senior Platform Engineer & SRE who runs production platforms on AWS, GCP and Azure. Companion to the Techworld with Randy episode Kubernetes Autoscaling and Cost.