Field Guides / RAG in Production
Field Guide · Intermediate to Advanced · 12-14 hours with labsRAG in Production for Platform Teams
Build, evaluate, secure and run a cited, permission-aware RAG assistant over your runbooks, from laptop to Kubernetes.
91
pages
pages
14
hands-on labs
hands-on labs
24
interview Q&As
interview Q&As
13
chapters
chapters
This is for you if
- You've been asked to put an AI assistant on your team's runbooks or wiki and make it production-ready
- A RAG demo works on ten questions and you need it reliable, secure and measurable
- You're a platform engineer or SRE moving toward AI engineering or ML platform roles
- You want senior-level answers to the RAG questions interviewers now ask
What's inside
- A complete, tested Python RAG service: FastAPI, pgvector, Ollama and the OpenAI-compatible API
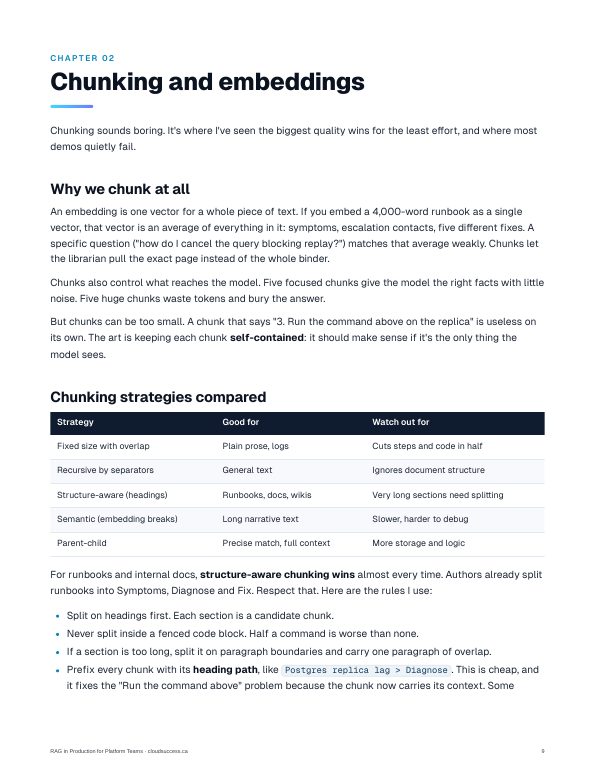
- Heading-aware chunking for runbooks, with overlap and code blocks kept intact
- Hybrid search with Reciprocal Rank Fusion in SQL and in Qdrant, plus cross-encoder reranking
- Why permission filters silently eat results in HNSW, and the pgvector iterative-scan fix
- Document-level permissions enforced inside retrieval, with an automated leak test
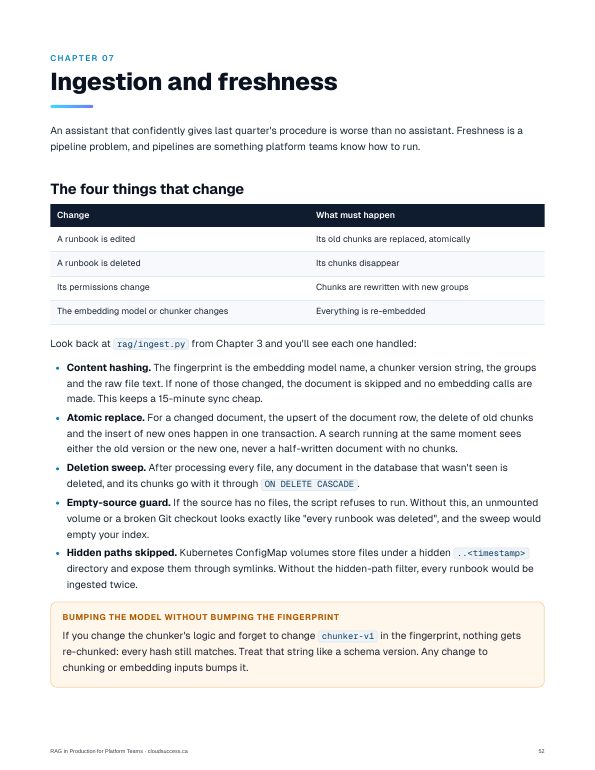
- Incremental ingestion that handles edits, deletions, ACL changes and the empty-mount trap
- An evaluation harness for recall@k, MRR, faithfulness and refusals, gated in GitHub Actions
- OpenTelemetry GenAI tracing and a full kind deployment with CloudNativePG, Ollama and Jaeger
- 14 hands-on labs, a troubleshooting playbook, 24 interview Q&As and a 30-day plan
After this guide you can
- Design and build a RAG service that cites sources and refuses when it doesn't know
- Choose between pgvector and a dedicated vector database, and tune HNSW for filtered search
- Prove that restricted documents never reach the wrong user, on every pull request
- Measure retrieval and answer quality, and block regressions in CI
- Trace, deploy and troubleshoot the whole stack on Kubernetes
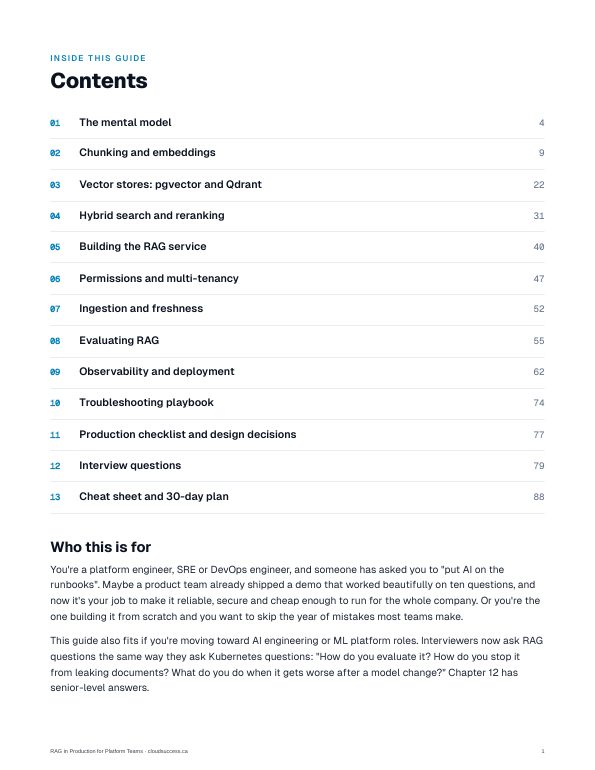
Contents
- The mental modelp. 4
- Chunking and embeddingsp. 9
- Vector stores: pgvector and Qdrantp. 22
- Hybrid search and rerankingp. 31
- Building the RAG servicep. 40
- Permissions and multi-tenancyp. 47
- Ingestion and freshnessp. 52
- Evaluating RAGp. 55
- Observability and deploymentp. 62
- Troubleshooting playbookp. 74
- Production checklist and design decisionsp. 77
- Interview questionsp. 79
- Cheat sheet and 30-day planp. 88
Written by Randy, a Senior Platform Engineer & SRE who runs production platforms on AWS, GCP and Azure. Companion to the Techworld with Randy episode RAG in Production.