Field Guides / SLOs and Error Budgets
Field Guide · Intermediate to Advanced · 9-12 hours with labsSLOs and Error Budgets in Practice
Choose SLIs users actually feel, do the error budget math right, and ship burn-rate alerts in Prometheus that you can unit test.
75
pages
pages
12
hands-on labs
hands-on labs
20
interview Q&As
interview Q&As
13
chapters
chapters
This is for you if
- You've been asked to set up SLOs and want more than a dashboard
- You run Prometheus and want alerts that page only when users hurt
- You're preparing for SRE or platform interviews
- You own a data pipeline or LLM feature and need real reliability targets
What's inside
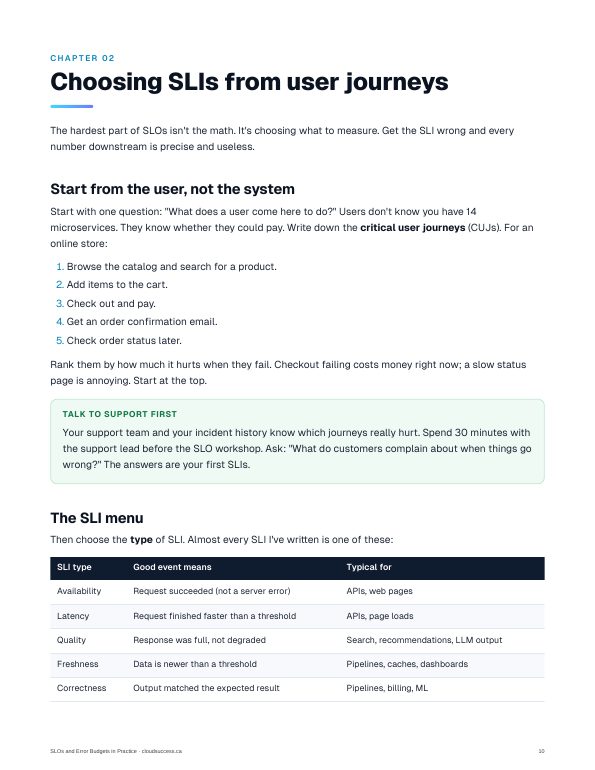
- Choosing SLIs from critical user journeys, with specification vs implementation
- The nines table and error budget math with worked examples, all checked
- Multi-window multi-burn-rate alerts derived from first principles (14.4, 6, 3, 1)
- Detection and reset time math, plus low-traffic strategies
- Layered Prometheus 3 recording rules, including the missing-numerator fix
- promtool unit tests that prove when alerts fire and clear
- What Sloth and Pyrra generate, line by line, and how they differ
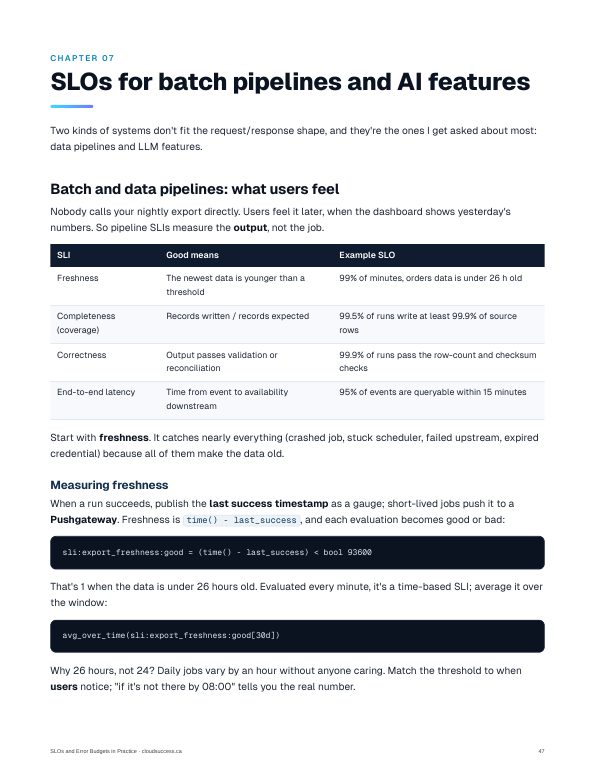
- SLOs for batch pipelines (freshness, completeness) and LLM features (valid output, TTFT, quality)
- Error budget policy, SLO review template, troubleshooting playbook and 20 interview Q&As
After this guide you can
- Turn a user journey into SLIs and a defensible SLO with a written rationale
- Compute budgets, burn rates, detection times and incident costs without guessing
- Implement and unit test burn-rate alerts in Prometheus, by hand or with Sloth or Pyrra
- Define freshness and LLM SLOs that catch failures HTTP codes miss
- Write an error budget policy and run an SLO review that changes decisions
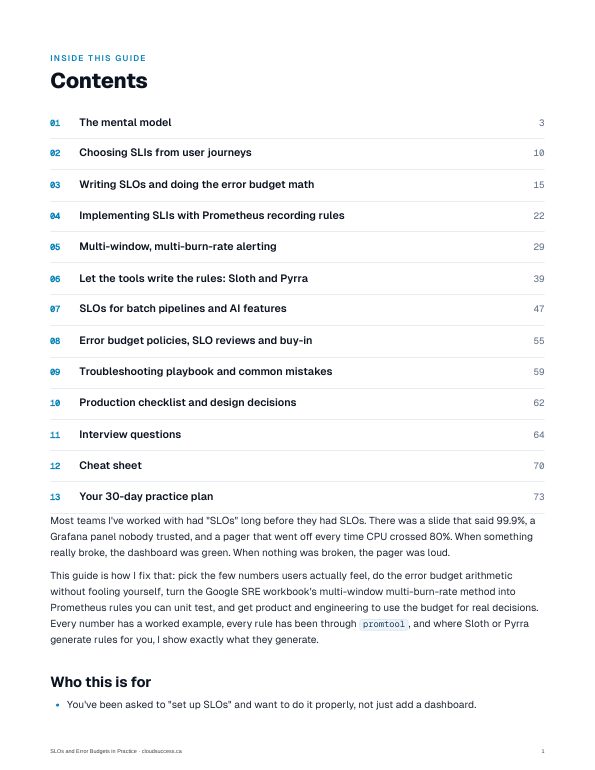
Contents
- The mental modelp. 3
- Choosing SLIs from user journeysp. 10
- Writing SLOs and doing the error budget mathp. 15
- Implementing SLIs with Prometheus recording rulesp. 22
- Multi-window, multi-burn-rate alertingp. 29
- Let the tools write the rules: Sloth and Pyrrap. 39
- SLOs for batch pipelines and AI featuresp. 47
- Error budget policies, SLO reviews and buy-inp. 55
- Troubleshooting playbook and common mistakesp. 59
- Production checklist and design decisionsp. 62
- Interview questionsp. 64
- Cheat sheetp. 70
- Your 30-day practice planp. 73
Written by Randy, a Senior Platform Engineer & SRE who runs production platforms on AWS, GCP and Azure. Companion to the Techworld with Randy episode SLOs and Error Budgets.